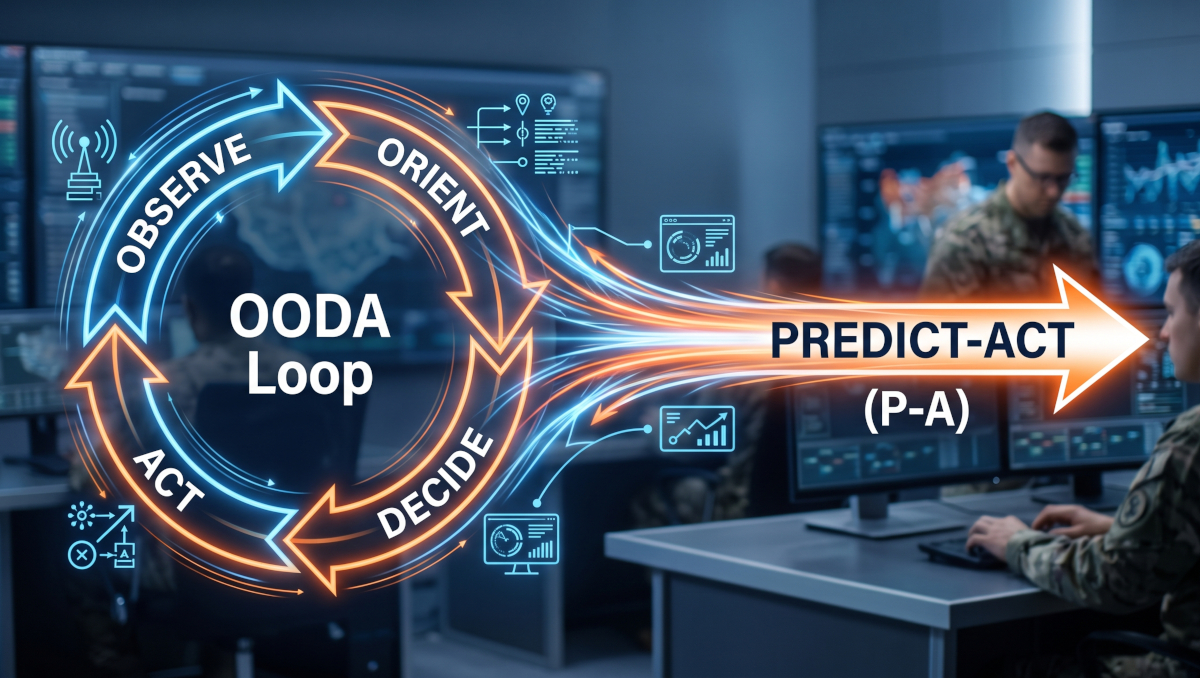
We are trading the reflection and adaptability of the circle for the velocity of the arrow.
The case for racing to dominate the cognitive domain is, by now, familiar. For years, strategists have argued that the army’s decisive, lasting advantage would be won not in the physical domain but in the cognitive one, where we know and act faster than an adversary. Finishing second in the race for artificial intelligence and intelligence amplification is unacceptable. This argument has taken hold, and the joint force is now running hard. But the urgency to finish first has produced a consequence few anticipated. In the rush to act faster than the enemy we may be dismantling the very decision model on which the original advantage was built.
For two generations, John Boyd’s OODA loop—observe, orient, decide, act—has shaped how the U.S. military thinks about decision advantage. Today, threats that move faster than human judgment are changing that loop. Driven by tactical necessity and often without awareness, the OODA loop is being transformed along a three-stage path toward a “predict-act” (P-A) vector.
This transformation represents a shift in the physics of command. A loop operates as an adaptive, circular system that self-corrects through feedback. By contrast, a vector acts as a straight, one-way arrow defined by direction and magnitude. In a P-A vector, the direction is the shortest line of action from prediction to execution, and the magnitude is the algorithm’s confidence score (see ‘Stage III,’ below). By collapsing the loop into a vector, we are trading the reflection and adaptability of the circle for the velocity of the arrow. This article traces that change across three stages and shows that it is already underway in fielded systems; further, it argues that the speed gained comes with risks we must proactively account for.
Stage I: Compressing Sensing — from Observe-Orient (O-O) to Recognition (R)
The first stage of this transformation occurs in how we “see” the battlefield. In modern conflict, the speed and volume of incoming data mean we can no longer afford the luxury of separate “observation” and “orientation” phases. To meet the demand for speed, we are merging these two steps into a single, automated state of Recognition (R), turning the decision cycle into R-D-A (recognize-decide-act). To recognize is to nearly instantly fuse inputs into a single understanding of the environment, allowing commanders to bypass manual observation and orientation. Instead of being overwhelmed with data, commanders receive a customized operational picture (the new COP) tailored to exactly how they process information.
Driven by the need to prevent cognitive overload, the transition from discrete sensing to integrated recognition is already running across multiple domains. In the air, the F-35’s fusion engine integrates feeds from its Active Electronically Scanned Array (AESA) radar, its electro-optical Distributed Aperture System (DAS), and secure tactical links, to project a single, coherent picture directly onto the pilot’s helmet visor, allowing the pilot to recognize a threat and react. On the ground, the same recognition compression reaches infantry squads through the Army’s Soldier Borne Mission Command (SBMC), which overlays terrain maps, drone feeds, and thermal target markers onto the soldier’s field of vision. At the operational level, under the Combined Joint All-Domain Command and Control (CJADC2) architecture, AI tools developed under Project Maven scan massive intelligence streams, converting raw sensor feeds into targets faster than any analyst could.
This transition aligns with Gary Klein’s Recognition-Primed Decision (RPD) model in cognitive psychology. Klein’s research shows that experienced leaders do not waste time comparing lists of options; instead, they instantly recognize a pattern and match it to an intuitive response. By fielding these technologies, the joint force has effectively automated that step. Near-instant recognition is now delivered directly to the decision-maker, compressing the observe and orient phases of the decision loop.
Stage II: The Emergence of Foresight — From Recognition (R) to Anticipation (A)
As Stage I matures, the joint force is already progressing into the second stage of the transformation: moving from R-D-A to A-D-A (anticipate-decide-act). Out of the urgent need to secure foresight before the physical battle begins, we are trading real-time reaction for active anticipation. To anticipate is to map out multiple branching future possibilities and options, allowing the force to proactively prepare for what an adversary might do next.
This shift toward automated anticipation is expanding across multiple echelons. During the Defense Advanced Research Projects Agency’s (DARPA) Air Combat Evolution (ACE) program, AI-controlled X-62A (Variable In-flight Simulation Test Aircraft) VISTA aircraft flew real-world maneuvers against human pilots, demonstrating that machine learning can preemptively position an aircraft, by anticipating aggressive human maneuvers before they occur.
In Ukraine, decentralized AI platforms coordinate swarms of drones, sharing target data and automatically reassigning roles in anticipation of jamming or other countermeasures. At the operational level, situational-awareness systems integrated with commercial AI platforms analyze historical enemy movement, supply paths, and terrain, to anticipate where an adversary is likely to establish defensive positions days in advance. In each case, the system is no longer recognizing what is happening; it is forecasting what is about to happen.
Stage III: The Hypersonic Vector—from Anticipate-Decide-Act (A-D-A) to Predict-Act (P-A)
At extreme speeds, the deliberate “decide” step becomes the bottleneck, and anticipation and decision (A-D) collapse into prediction (P) resulting in a direct predict-act (P-A) vector. In this model, predicting means calculating a single optimized outcome with an assigned confidence score and providing the immediate data trigger to execute automated action. The confidence score is not the new component that defines P-A because probabilistic forecasting systems like weather models and AI-enabled targeting tools already do that. The distinction is that once a prediction crosses a preset confidence threshold, the system triggers action automatically, with no human decision in between. In this new model, the person no longer decides whether to act. Instead, the person sets in advance the conditions under which the machine will act.
It is important to fully appreciate the P-A framework. Boyd’s logic of advantage was out cycling the adversary. That is, running your own OODA loop faster than the adversary could run theirs, presenting them with dilemmas they could not process in time (an overwhelming tempo of threats). The logic of P-A is different. It wins by out-predicting and preempting the adversary. It seeks to forecast the adversary’s move with enough confidence to act first, effectively shutting down adversary options before they are exercised. In doing so, the system predicts what will happen without necessarily understanding why. Prediction, not comprehension, becomes the basis for action. This is the implication at the heart of the P-A vector, and it is the source of the risks that follow.
The P-A vector is already deployed across several limited systems in modern combat. At the tactical defensive edge, automated air-defense systems such as the Aegis Combat System, the Phalanx Close-In Weapon System, and the Iron Dome represent the extreme of this compression: their tracking algorithms predict where a fast-moving threat will be in the future and fire interceptors automatically. The same logic now appears on the offensive end in Ukraine, where mass-produced first-person view (FPV) drones use onboard AI-guided terminal navigation to predict a target’s vector under heavy jamming and execute the final attack autonomously. At the operational level, predictive analytics increasingly generate friendly courses of action with explicit confidence levels. This dynamic is moving the commander’s role from choosing from various options in the moment to pre-authorizing the conditions under which an option is automatically executed.
Because predictive models are trained on historical data, they are blind to “Black Swan” events that a creative adversary could deliberately use to hide its actions.
The Reality of What We Are Up Against: Risks and Blind Spots
Because this transition to a predict-act framework is occurring across many different systems, we must proactively design safeguards. Deep neural networks like those in many AI models are easily fooled by adversarial spoofing, so an enemy can feed “synthetic anomalies” into our sensors, tricking our AI into executing predictable preemptive actions that play directly into their hands. And because predictive models are trained on historical data, they are blind to “Black Swan” events that a creative adversary could deliberately use to hide its actions.
Predict-Act also introduces the very real threat of cascading failure. Commercial high-frequency trading (HFT) is a good example. In HFT, AI algorithms predict very small market movements and execute millions of trades in microseconds, with no human in the decision path (the P-A vector). On May 6, 2010, those systems produced the “Flash Crash” in which competing HFT algorithms drove the market into a “crash” that erased roughly a trillion dollars in value in minutes, well faster than any human could intervene.
Now transpose that dynamic onto a crisis between nuclear-armed states. A minor sensor glitch or a deliberately injected synthetic anomaly could lead one side’s AI to a high-confidence ‘mis-prediction,’ which could auto-trigger a preemptive action, which in turn could trip the adversary’s similarly automated P-A response. In seconds, both sides could slide into an uncontrollable “algorithmic flash war” before human leaders can register that a crisis has begun. This is the danger of fielding predict-act systems that act on prediction without understanding: they will fail beyond the reach of the humans nominally in charge.
The Commander’s New Art
The transition from OODA to R-D-A, then to A-D-A, and finally to a predict-act vector is our current trajectory. We are moving there out of urgency and necessity, but perhaps without realizing how far we have already traveled. Whether P-A is the OODA loop’s evolution or its quiet replacement is, in the end, an academic question; the systems are being fielded either way, and the risks are the same. What matters is that we recognize the shift and govern it deliberately rather than stumble into it.
To mitigate these risks, our networks must integrate cognitive “circuit-breakers” and anomaly filters that alert commanders to strategic deception. Crucially, the “act” component of any P-A vector must include non-kinetic, defensive, or “silent standby” postures as automated defaults, so that the reflexive response to uncertainty is restraint rather than escalation.
Managing these systems also requires a new set of commander-driven tools designed specifically to prevent a “human-out-of-the-loop” situation, where automated speed creates a human-less vulnerability. First, commanders must actively articulate acceptable confidence levels. For example, they must raise the required confidence score to near-certainty in a murky gray-zone crisis to prevent accidental escalation, while lowering the threshold in high-tempo, defensive operations where the speed:survival ratio is high. Second, commanders must enforce algorithmic red-teaming, standing up specialized teams to aggressively probe and spoof their own AI systems to expose blind spots before the enemy can exploit them. Finally, to counter the danger of staff complacency and loss of cognitive fitness, leaders must mandate randomized cognitive audits, forcing their staffs to manually reconstruct the data-logic behind machine-generated plans to preserve active, critical human thinking.
All these safeguards are commanders’ business, and leaders must truly understand how they work. In a predict-act era, the commander’s role shifts fundamentally from executing real-time actions to managing the strategic bounds of ‘what we are allowing machines to do.’ The commander’s biggest responsibility may no longer be to fight the battle, but to engineer and program the limits of the fight and to place “humans-before the-loop (or vector).” This shift defines the future “art” of warfighting. Designing, adjusting, and enforcing these algorithmic guardrails will become the single most critical component of a commander’s intent.
Sam White is the Deputy Director of the Center for Strategic Leadership at the U.S. Army War College.
The views expressed in this article are those of the author and do not necessarily reflect those of the U.S. Army War College, the U.S. Army, or the Department of War.
Photo Credit: Created by Gemini
Question. Why did Boyd put all those arrows, those feed-forward and feedback pathways in his OODA loop? What does IG&C represent?
Didn’t Karl Friston, the most cited neuroscientist in the world, the person behind the Free Energy Principle and active inference, say that Boyd’s real OODA loop is isomorphic with active inference.
Active inference includes predictive processing as its core perceptual mechanism and generalizes it to action, planning, and learning.
Is it possible that you are using the four step OODA loop as THE model of the OODA loop?
Did you know we have over 180 episodes where we explore Boyd’s REAL OODA loop from different domains? We even had Gary Klein on the pod.
LLMs are closed systems. They are modeled after the closed OODA loop, the four step process, the one Boyd didn’t sketch. LLMs often create linear OODA slop.
From the beginning of our article above:
“The case for racing to dominate the cognitive domain is, by now, familiar. For years, strategists have argued that the army’s decisive, lasting advantage would be won not in the physical domain but in the cognitive one, where we know and act faster than an adversary.”
Herein, and by way of the matter that I present below, should we not be looking at “the cognitive domain” differently; that is — not from the perspective of being “faster” — but more from the perspective of being “better,” “more influential,” “more successful” and, importantly, more “human?”
As to that such suggestion, consider the excerpt below, from the beginning of the Sep 16, 2025, Alexander Hamilton Society — Security and Strategy Journal — article “How the United States Can Fight and Win in the Cognitive Domain” by Max Lesser:
“In May 2024, U.S. troops began withdrawing from Niger after the country ended a military agreement several months earlier that allowed the U.S. Department of Defense to operate from the country. A Nigerien military spokesman provided a murky explanation for his country’s decision, characterizing the previous agreement with the United States as ‘profoundly unfair’ and claiming that it did ‘not meet the aspirations and interests of the Nigerien people.’
General Michael Langley, head of United States Africa Command, placed the blame for the withdrawal of U.S. troops squarely on Russia in his March 2024 congressional testimony. Gen. Langley claimed that the ‘Russian Federation’s narrative drowned out the U.S. government’s in the past years… across the Sahel,’ where Russia conducted aggressive and savvy ‘misinformation [and] disinformation campaigns.’ It is likely not a coincidence that, weeks after Niger ended its military agreement with the United States, Russian troops began operating out of the same military base U.S. troops had used.
Russian adversarial influence operations in Niger contributed to tangible consequences for the United States—not merely a nebulous decrease in pro-U.S. sentiment, but the loss of a military base that cost the U.S. taxpayer over $280 million. On top of this financial loss, the U.S. withdrawal from Niger allows Russia to easily deploy drones in Niger to threaten the North Atlantic Treaty Organization’s (NATO) southern flank and Iran to access Niger’s uranium reserves. These threats are not merely hypothetical. Iran purchased 300 tons of concentrated uranium from Niger after the expulsion of U.S. troops. America has not merely lost a popularity contest with Russia in Niger, losing the cognitive war to Russia has increased America’s strategic threats.”
Thus:
a. If, as per the beginning of our WRB article above, “lasting advantage would be won not in the physical domain but in the cognitive one,”
b. Then, accordingly, should we not be looking at the “cognitive domain” differently, for example, from the perspective of the excerpt from the Security and Strategy Journal that I provide above?
(Otherwise, we would not seem to be discussing “the cognitive domain” but, rather, something more akin to a non-human AI cognitive domain?)
At my final, in-parenthesis paragraph above, should I simply have said “AI domain;” this, rather than “non-human AI cognitive domain?”
Sam, this maps a real and urgent trajectory. The shift from OODA toward what you call Predict-Act is already visible in fielded and emerging systems, and your warning about Black Swan blindness, synthetic anomalies, and a flash-crash-style flash war is timely.
I’d push back on the treatment of Boyd and Klein that underwrites the cure.
First, Boyd. You describe Stage I as a merger of Observe-Orient into Recognition, turning OODA into R-D-A. It is a clean narrative, but it preserves the popular sequential reading of OODA more than Boyd’s mature model.
In Destruction and Creation and in the fuller OODA sketch, Orientation is not simply the second step. It is the central, continuously active engine, shaped by cultural traditions, genetic heritage, previous experience, and new information and analysis. It shapes Observation itself. It provides implicit guidance and control for Decision and Action. It is the dialectical process through which we destroy old mental models and build new ones.
Snowmobiles.
Recognition, the fused, tailored operational picture, is less Orientation than better, algorithmically curated Observation. It may improve the channel without protecting the process that produces the output.
That distinction matters. The issue is not principally predictions, which are outputs. The orientation architecture determines which predictions seem plausible, which anomalies register as meaningful, and whether the organization retains the will to destroy its own working model. Merging Observe-Orient into Recognition does not speed Orientation. It may bypass it.
Second, Klein. You align Recognition with Recognition-Primed Decision-making: experienced leaders recognize a pattern rather than compare options, and machines increasingly automate that recognition. The analogy tracks Kahneman’s System 1. But Klein’s account is more demanding than pattern-match automation.
Recognition-Primed Decision-making involves four linked capacities: reading cues and forming expectancies, detecting anomalies (what should be present but is not), mentally simulating a course of action far enough to see where it fails, and building a causal story that makes the situation intelligible.
Automating pattern classification may capture the first component. But unless the system deliberately preserves anomaly detection, mental simulation, and causal storybuilding as human tasks, it risks displacing the other three. Those three are where judgment matters most amid deception, novelty, and incomplete information.
Third, confidence as history. You frame P-A as direction plus magnitude, with confidence as magnitude. But confidence is not neutral physics. It is calcified history: training data, labels, reward functions, assumed enemy behavior, and institutional choices made months or years before deployment. A model carries a pre-deployment orientation into theater before any theater exists.
That is a temporal problem. Operational planning focuses on the contingency or campaign. Cognitive weathering happens earlier, shaping the social and institutional constructs that service members, staff, and systems carry into theater. If that architecture has already normalized certain labels, incentives, and expectations, the anomaly may not register as anomalous at all.
This changes mitigation. Circuit breakers, anomaly filters, non-kinetic defaults, confidence thresholds, red-teaming, and cognitive audits are necessary, but they protect channels. They manage outputs. We also need process protection: disciplined pauses that let deliberate human judgment intercept algorithmic output before it moves from System 0 prediction through rapid System 1 acceptance into effect. Is this label a fact or a probability, and what single indicator would most alter our assessment?
These are not calls for hesitation. They are cognitive pause points, calibrated by echelon and consequence.
We are not merely trading the reflection of the cycle for the velocity of the arrow. We risk hollowing out the Orientation that made the circle adaptive in the first place.
John R. Boyd, Destruction and Creation, 1976. https://e1z.ca/lifeonomics/2023-04-20_ExpertsEcho_John_Boyd/johnboyd_docs/04_Destruction_and_Creation.pdf
John R. Boyd, Patterns of Conflict, 1986. https://www.coljohnboyd.com/; see also Frans Osinga, Science, Strategy and War.
Gary Klein, Sources of Power: How People Make Decisions (MIT Press, 1998), ch. 2–4, on cues, anomaly detection, mental simulation, and story building.
Bill Ault, “The Beautiful Question,” https://billault.substack.com/p/the-beautiful-question
Bill Ault, “The Commander’s Firewall,” https://billault.substack.com/p/the-commanders-firewall
Given the question: Does the OODA decision loop depend on strategy, AI answered as follows:
“Yes, the OODA decision loop must be deeply dependent on strategy, because its core “Orient” phase relies directly on your background, goals, and strategic framework to make sense of incoming information.”
If this is correct, then (a) are we/they not by-passing strategy — and, thus, one’s background, goals, and strategic framework — by going the Predict-Act, etc., alternative routes; this, (b) making these alternative routes, accordingly, less and/or non-useable — and/or — simply nonsensical?
In the “strategy-out-of-the-loop” circumstances, that I describe above, what does the commander do/how does the commander compensate?
In the “strategy-out-of-the-loop” circumstances, that I describe above, how can the Act phase be — intelligently — formulated?